Operating a neighborhood LLM and a sport on the identical PC normally means one among them can have a nasty time. A typical gaming GPU with 16GB of VRAM might need sufficient reminiscence for an honest mannequin or a sport, however working each on the similar time? That is a fairly tall order, and it will doubtless trigger information to spill over into your slower system RAM.
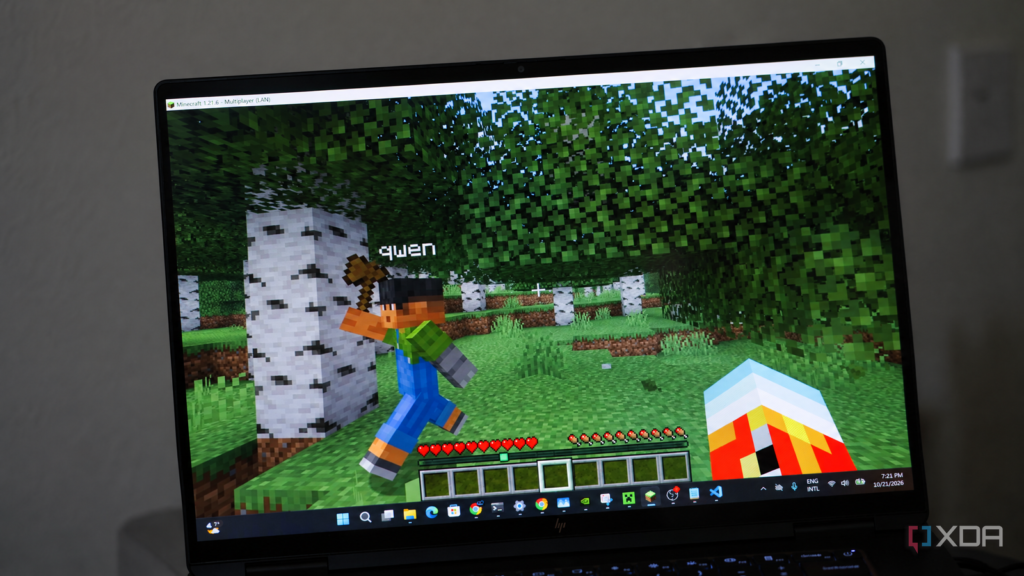
Utilizing the HP OmniBook Extremely 16, packing Nvidia’s RTX Spark, combines a 20-core Arm CPU and a 6,144-core Blackwell GPU with 128GB of unified memory. Utilizing Qwen 3.8 Flash Subsequent, a 125-billion-parameter mixture-of-experts mannequin, I used to be in a position to invite a bot to a Minecraft world over LAN. And due to the 128GB of VRAM, I used to be in a position to play Minecraft and have the mannequin management the bot on the similar time.
Is it good? Completely not; the bot takes some time to reply, often guarantees gadgets it would not have, and at one stage, jumped right into a gap within the floor earlier than disconnecting from the server. With that stated, it really works, and Minecraft was working at round 120 FPS for a lot of the session, even with the mannequin working alongside it.
Mindcraft turns a language mannequin right into a Minecraft participant
Not an excellent one, thoughts you

The bot makes use of Mindcraft, an open-source challenge constructed on Mineflayer, a Node.js library for creating Minecraft bots. Mindcraft connects the bot to your world like some other participant, and also you work together with it by means of the in-game chat. If you ask it to do one thing, the mannequin has instruments out there to it that come by means of within the type of instructions. For instance, I requested it to deliver me 10 birch longs, and it despatched “!collectBlocks(“birch_log”, 10)” into the chat earlier than going forward to just do that. Mindcraft handles the precise motion, mining, and stock administration, whereas the mannequin decides what to do and narrates its actions.
Setting it up is simple. I opened my Minecraft world to LAN on a set port, linked Mindcraft to it, and ran node principal.js. That additionally launches an online dashboard exhibiting the bot’s well being, place, and stock. Mindcraft would not have a devoted llama.cpp possibility, however its LM Studio integration makes use of an OpenAI-compatible API with a configurable deal with, so I pointed it at my native llama.cpp server.
It’s also possible to arrange imaginative and prescient, and instructions corresponding to !lookAtPlayer seize a picture from the bot’s perspective and ship it to the mannequin, permitting it to see what’s taking place round it. Mindcraft additionally contains premade duties, starting from accumulating 4 logs to constructing a church from a blueprint, that are helpful for testing the bot instantly and guaranteeing that it really works.
It’s also possible to have the mannequin run JavaScript in your pc, by means of a !newAction command. I left this switched off, but it surely means you’ll be able to ask it to do issues exterior of the sport with the outputs piped again into the sport chat.
The mannequin and the sport share the identical reminiscence
However one would not have an effect on the opposite

Nvidia supplies llama.cpp recipes for working fashions on RTX Spark, and I used the Qwen3.8-Flash-Subsequent recipe to get issues up and working. This contains vision support and an MTP draft mannequin for speculative decoding, with llama.cpp serving the mannequin by means of an OpenAI-compatible API on port 9931. Earlier than launching Minecraft, I measured roughly 46 tokens per second at a brief context, dropping to only underneath 42 at 32,000 tokens.
Qwen 3.8 Flash Subsequent is a mixture-of-experts mannequin with 125 billion parameters, however solely round 6 billion are energetic per token, and its 51-billion-parameter n-gram embedding is streamed from storage fairly than stored solely in reminiscence. It makes use of an enormous quantity of reminiscence for a neighborhood LLM, however the laptop computer’s 128GB unified reminiscence pool signifies that there’s greater than sufficient room to run Minecraft alongside it.
Higher but, Minecraft runs natively on Home windows on Arm, with Arm64 builds of Java and the required graphics libraries, so there is not any want for Microsoft’s PRISM x86 emulation. I used to be getting round 120 FPS for a lot of the session, even with the mannequin working alongside it.
There additionally would not have to be any particular preparations made in relation to GPU scheduling to ensure that this to work. Nvidia has its NVIGI SDK which helps optimizations for working AI workloads alongside video games, however its CUDA in Graphics function is not presently supported on RTX Spark. In different phrases, the llama.cpp server and Minecraft are each sharing GPU assets with out these optimizations, however fortunately, Minecraft is not a very demanding sport. I’ve beforehand run Cyberpunk 2077 at 1440p on a ThinkStation PGX utilizing the identical GB10 silicon, and I would count on a sport of that calibre to endure an entire lot extra if a 125B mannequin had been working alongside it.
It handles easy jobs effectively sufficient
Birch logs, saplings, and grime
As soon as Qwen joined my world, it proceeded to behave like an keen however barely confused buddy. It greeted me, narrated every little thing it was doing, and requested for directions when it was idle. Once I instructed it to gather birch logs, it despatched a message that stated !collectBlocks(“birch_log”, 10), walked to the closest timber, and began chopping. There is a noticeable delay between asking it to do one thing and seeing it act, because the mannequin must course of the dialog and generate its subsequent command.
Gathering supplies is arguably the place it really works finest; after it collected all of these birch logs, I requested it handy over the saplings it had picked up as effectively from the decaying timber. It replied “Positive, listed here are your saplings,” walked over, and dropped eight of them at my toes. It is fairly cool to see, so I upped the ante a bit. I requested it to gather roughly 30 blocks of grime, and it replied “On it” earlier than digging straight into the bottom. That did not go fairly as easily.
The respones aren’t canned, which is good. When it joins the server (or rejoins), it’s going to give a singular greeting generated by the language mannequin itself. It is a fairly small element, but it surely provides to the expertise of feeling such as you’re taking part in with one other individual than a script that is simply executing instructions.

The bot makes loads of errors, too. Once I first requested it handy over the birch logs it had collected, it replied “Positive, right here you go” and tried to provide me ten. There was only one drawback: it did not have any, as a result of I had put it in Artistic mode at first by mistake. Mindcraft’s logs, although, stated that it by no means obtained the gadgets, and the mannequin shortly corrected itself: “I haven’t got any birch_logs in my stock proper now. Let me collect them once more for you.” It is a fairly human technique to deal with being caught out, at the very least.
On a number of events, the bot tried to name the !newAction command regardless of it being disabled. For instance, it could generate a plan to do a job I had requested it, like “Accumulate 5 extra birch logs utilizing the picket axe,” solely to find that code writing wasn’t allowed. It might acknowledge the restriction in chat and provide to make use of Mindcraft’s normal instructions as an alternative, which it ought to have finished from the start.
On its quest to gather extra birch logs once I requested, the bot took a working bounce straight right into a gap, earlier than instantly leaving the sport as quickly because it fell. A number of seconds later, it got here again, introduced that it was “Selecting up merchandise!”, and carried on as if nothing had occurred. It then dropped me the birch logs I would requested for. Fairly neat.

Amassing grime was a bit peculiar, too. The bot dug itself right into a pit, sat there for some time, earlier than asserting “I am caught!” adopted by “Exiting.” earlier than disconnecting once more. These errors come from Mindcraft’s built-in unstuck system, which might detect when the bot hasn’t moved for 20 seconds whereas finishing up a job. It first tries to maneuver 5 blocks away, but when that fails after one other ten seconds, it terminates the agent earlier than attempting once more. As soon as it had rejoined, it introduced “Obtained caught there for a sec. Retrying now.” and resumed digging. A few minute later, it moved over to me and dropped me half a stack of grime blocks.
These navigation issues aren’t brought on by the mannequin, nor have they got something to do with efficiency. Mineflayer’s pathfinding has some points, and the mannequin will depend on Mindcraft to execute its directions. It may possibly resolve to gather ten logs, however really reaching the timber and accumulating them is one other matter. For probably the most half, the mannequin understood what I needed, even when the bot struggled to hold it out.
I wasn’t actually impressed by how clever the bot was (in truth, a number of amusing situations form of swung the opposite means), however I used to be impressed that I may run your entire experiment on the identical machine. Minecraft ran at principally 120 FPS your entire time, whereas a 125-billion-parameter mannequin generated responses and determined what to do subsequent within the background. The entire inference occurred on the identical machine, and not using a cloud API, and due to the 128 GB of VRAM on board, I did not have to compromise on the scale of the mannequin simply to make room for the sport.
Largely, although, it is simply enjoyable to mess around with.